
How Does Machine Learning Improve Demand Planning Accuracy?
TIME
Click count
Machine learning improves demand planning accuracy by learning how sales respond to combinations of factors, including price, promotions, seasonality, availability, and local conditions. It can share information across related products and update forecasts as new observations arrive. These capabilities are especially useful when demand patterns vary across locations or change in ways that simple historical averages cannot capture.
The improvement is conditional: richer models need reliable data, relevant signals, and evaluation against credible alternatives. Stable demand may be forecast just as well by a simple statistical method. The strongest evidence of value is lower forecast error at the product, location, and planning horizon where purchasing or replenishment decisions actually occur.
Where machine learning changes the forecast
Traditional forecasting methods such as exponential smoothing and seasonal ARIMA describe patterns within a time series. They offer useful baselines when demand follows a reasonably consistent level, trend, or seasonal cycle. Statistical models can also incorporate external variables, so using weather or promotions does not automatically make a forecasting approach machine learning.
The distinction becomes more useful when examining how relationships are learned. Machine learning methods, including gradient-boosted trees and neural networks, can capture nonlinear effects and interactions without requiring every relationship to be specified in advance. A discount, for example, may have a different effect during a holiday, on a premium product, or when a competing item is unavailable.
There is no universal winner. A portfolio can retain statistical forecasts for predictable items while applying machine learning where complexity produces measurable gains. Comparing both approaches under the same data and timing constraints prevents an apparent technology advantage from being caused simply by better inputs.
Why combinations of signals matter
Consider a seasonal outdoor product. Recent sales alone cannot distinguish a sustained increase in demand from a temporary response to warm weather and a promotion. A model that combines temperature forecasts, calendar information, planned discounts, and sales history has more evidence for estimating what happens after the promotion ends.
Interactions matter because effects are rarely constant. A price reduction may generate little additional demand immediately after a previous promotion pulled purchases forward. Weather sensitivity may differ between regions. An industrial replacement part may follow installed equipment populations and maintenance schedules more closely than broad calendar seasonality.
Useful inputs must match the decision horizon. A short-range weather forecast can support near-term replenishment, but it cannot describe conditions months ahead with the same precision. Longer-horizon forecasts need appropriate assumptions, seasonal information, or scenarios. Giving a model actual future weather during testing would exaggerate its practical accuracy.
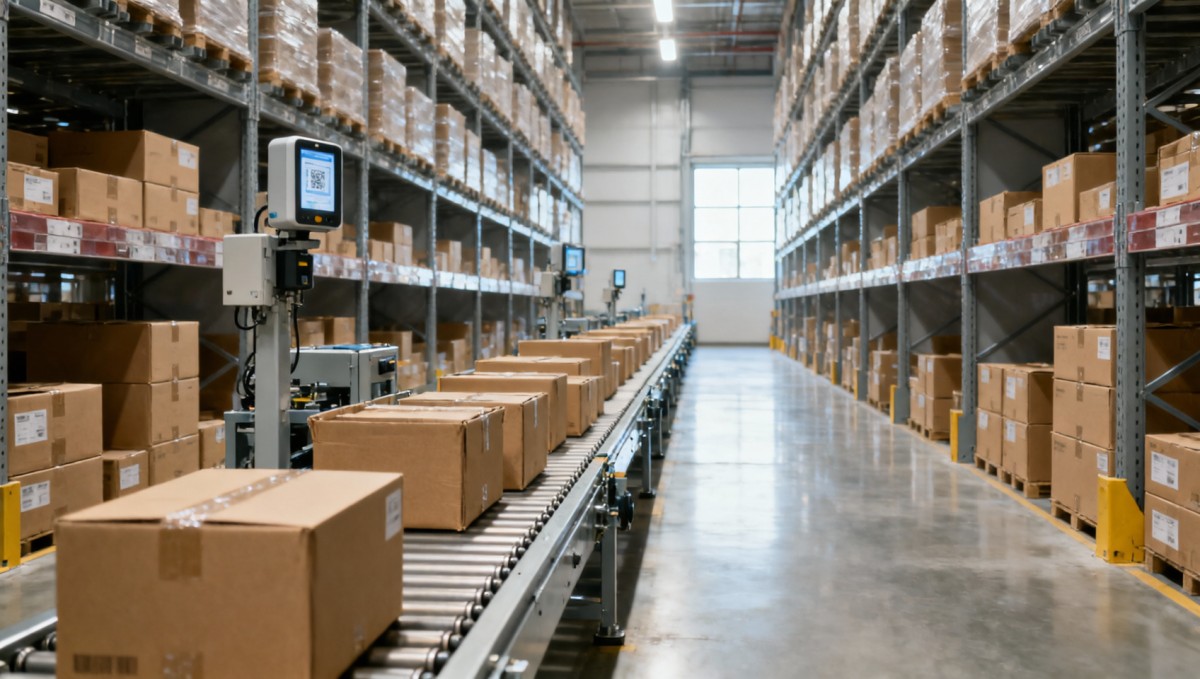
Shared learning also changes what is possible with sparse product histories. A model trained across related items can use attributes such as category, pack size, application, and price position to estimate demand for an item with few observations. This is useful for assortment changes, although a genuinely new product with no close analog remains difficult to forecast.
Product relationships require care. A promotion can shift sales from one pack size to another without increasing total category demand. Forecasting each item independently may interpret the promoted item's increase as entirely new consumption. Including substitution signals or coordinating forecasts across the product hierarchy helps expose that distinction.
Sales history can hide the demand being forecast
Recorded sales are an imperfect measure of demand whenever availability constrains purchasing. An item that sells nothing because it is out of stock looks very different from an available item that attracts no orders. Without inventory or availability data, a model can learn to predict the shortage itself and repeatedly underestimate demand.
Relevant records include stock availability, backorders, cancellations, returns, and fulfillment restrictions. Their meaning must be defined consistently. A backorder fulfilled later should not automatically count as fresh demand on the shipment date. Returns can distort net sales if their timing is disconnected from the original purchase.
Order patterns introduce another ambiguity. A distributor placing a large replenishment order may be building inventory rather than responding to equivalent growth in final consumption. If downstream sales are unavailable, the forecast concerns orders received, with their associated batching behavior. Calling that output consumer demand creates a misleading interpretation even when the predictions are accurate.
Changes in product codes, pack quantities, and reporting calendars also create artificial breaks. A replacement item may inherit demand from its predecessor, while a unit-of-measure change can resemble a sudden volume surge. These issues need explicit treatment before model training; additional algorithmic complexity does not resolve an inconsistent sales record.
Proving that accuracy improved
A credible comparison recreates past planning decisions. Train each method using only information available at a historical cutoff, generate forecasts for the required horizon, and compare them with subsequent observations. Repeat the exercise across multiple cutoffs so that performance reflects different seasonal and operating conditions.
This rolling evaluation is more informative than randomly splitting rows into training and test sets. Random splits can expose the model to later observations or closely related records that would not have been available when the forecast was issued.
The horizon must match the action. If replenishment depends on demand throughout a supplier's lead time, evaluate cumulative demand over that period. A model that excels at tomorrow's sales may perform poorly over the period covered by an order. Likewise, a strong monthly total can conceal errors in the weekly timing needed for production scheduling.
Use metrics that reveal different failure modes
Mean absolute error expresses the average miss in the original units, making it interpretable within a product series. Weighted absolute percentage error, calculated from total absolute error relative to total actual demand, summarizes a portfolio but gives greater influence to high-volume items. It is undefined when the evaluated total actual demand is zero.
Mean absolute percentage error becomes unstable around very small actual values and is undefined at zero, making it unsuitable for many intermittent-demand comparisons. Scaled metrics can support comparisons across series, although their reference errors also need scrutiny when histories are constant or sparse.
Bias deserves a separate measure. A forecast can achieve acceptable average error while repeatedly underpredicting demand. Conversely, excessive forecasts may conceal availability problems by maintaining more inventory than necessary. Reviewing signed error alongside absolute error exposes the direction of the misses.
Results should also be separated by demand pattern, product maturity, location, and forecast horizon. An improvement dominated by a few large sellers can hide deterioration across many slow-moving items. Forecast accuracy and operational outcomes are related, but inventory performance also depends on replenishment rules, lead-time variability, and service targets.
When uncertainty matters more than a single number
A point forecast gives one estimate, often an expected value or median. Inventory decisions also depend on the range of plausible demand. Probabilistic forecasting estimates that range through prediction intervals or quantiles, allowing different replenishment choices when the cost of a shortage differs from the cost of excess stock.
A higher demand quantile can support a more cautious inventory position, but it is not automatically equivalent to an achieved service level. That relationship depends on the replenishment policy, lead time, and how service is measured. Variable lead times require attention to demand across a variable coverage period.
Probabilistic forecasts need their own validation. A prediction interval should contain actual demand at approximately its stated frequency across repeated forecasts. Intervals that are consistently too narrow create false confidence; excessively wide intervals offer limited guidance. Quantile loss and coverage analysis help assess this tradeoff.
Irregular spare-parts demand illustrates the limitation of a single average. The same average volume could arise from frequent small orders or occasional large ones, with very different inventory implications. A model that estimates the probability of an order separately from its likely size can represent this behavior more usefully, provided the historical record contains enough relevant events.
Keeping improvements after deployment
Updating forecasts with new observations and retraining a model are separate activities. A trained model can issue fresh predictions using current inputs without relearning its underlying relationships. Retraining becomes useful when accumulated data or changing behavior supports a better model; doing it more often does not guarantee improvement.
Monitoring should connect changes in error to their likely causes. Missing promotion data, delayed transactions, a new ordering policy, and a genuine demand shift call for different responses. If a key input disappears, a tested fallback forecast is more dependable than silently substituting arbitrary values.
Human adjustments remain useful when relevant information has not entered the data, such as a confirmed contract, a planned closure, or a discontinued product. Each override should preserve the original forecast and record its reason. Comparing adjusted and unadjusted results later reveals whether intervention adds information or introduces recurring bias.
The decision to retain machine learning should rest on sustained performance against a maintained baseline. Where it improves the relevant horizon and captures useful demand variation, the added complexity is justified. Where simpler forecasts remain equally accurate, retaining them preserves a clear and economical planning process.
Recommended News
- How Does Machine Learning Improve Demand Planning Accuracy?Oct 27, 2026How does machine learning improve demand planning accuracy? Discover key data signals, forecasting methods, and validation tips to reduce errors and make smarter inventory decisions.
- AI Procurement Workflow Automation: Where to Keep Human ApprovalOct 21, 2026Explore ai tools for automating procurement workflow best practices: discover where to keep human approval, reduce risk, and accelerate purchasing with smarter controls.
- How Can You Verify an AI Vendor Has Real Manufacturing Data?Oct 12, 2026How to verify if an AI tool vendor has real manufacturing data: discover provenance checks, legal safeguards, and factory-fit tests to avoid costly mistakes and choose with confidence.
- Do AI Manufacturing Inspection Tools Actually Reduce Inspection Time?Sep 16, 2026Do AI tools for manufacturing actually reduce inspection time? Discover where AI vision saves time, what affects ROI, and how to pilot smarter quality control.
- How Intelligent Data Analysis Dashboards Turn Operational Data Into Actionable DecisionsAug 30, 2026Intelligent data analysis dashboard: turn project data into clear, timely actions. Spot risks, control costs, protect schedules, and improve operational decisions.
- Product Safety for Green Materials: Selecting Chemical Tests by End UseOct 29, 2026Product safety for green materials starts with end use. Learn how to select emissions, migration, and chemical tests to close evidence gaps and support credible safety claims.
- CNESA Approves Lithium-Plating Test Standard Project for Energy Storage BatteriesOct 29, 2026CNESA approves a lithium-plating test standard project for energy storage batteries. Explore potential impacts on battery testing, supplier evaluation and procurement.
- TBEA’s 29 New Energy and Power Equipment Products Pass National-Level AppraisalOct 26, 2026TBEA’s 29 new energy and power equipment products reportedly passed national-level appraisal. Explore the results and key checks for smarter procurement decisions.
- Baby Sleeping Bags: Choosing the Right TOG Rating and a Safe FitOct 25, 2026Choosing babysleepingbags? Discover how to match TOG ratings to room temperature, check for a safe fit, and avoid overheating with practical tips to help you shop confidently.
- Eco Building Solutions in the UAE: Estidama vs. Al Sa'fat RequirementsOct 21, 2026Explore eco building solutions UAE projects need. Compare Estidama and Al Sa’fat ratings, technical requirements and compliance evidence to reduce approval risks and choose with confidence.
- Outdoor Furniture Prices by Material: Purchase, Delivery, and Upkeep CostsOct 27, 2026Compare outdoor furniture price by material, including purchase, delivery, and upkeep costs. Discover how to evaluate supplier quotes and choose better long-term value.
- Real-Time Industrial Trend Analysis: Which Indicators Signal Demand Shifts?Oct 23, 2026Use real time industrial trend analysis to spot demand shifts early. Discover how orders, inventory, and factory activity reveal buying signals and guide smarter business decisions.
- Global Sourcing for Procurement: How to Compare Total Landed CostsOct 22, 2026Optimize global sourcing for procurement by comparing total landed costs, from freight and duties to quality risks. Discover how to uncover hidden costs and choose suppliers with confidence.
- How Can Data Analysis Compare Global Supplier Pricing Trends?Oct 12, 2026How to use data analysis to compare global supplier pricing trends? Learn to align quotes, track currency impacts, and compare landed costs for smarter sourcing decisions.
- Vietnam Precast Concrete Market: Demand Drivers, Capacity, and Buyer RisksOct 09, 2026Vietnam precast concrete market insights: assess demand drivers, production capacity, logistics, quality compliance, and buyer risks for smarter sourcing and investment decisions.
All Categories
Hot Articles
- Product Safety for Green Materials: Selecting Chemical Tests by End UseOct 29, 2026Product safety for green materials starts with end use. Learn how to select emissions, migration, and chemical tests to close evidence gaps and support credible safety claims.
- CNESA Approves Lithium-Plating Test Standard Project for Energy Storage BatteriesOct 29, 2026CNESA approves a lithium-plating test standard project for energy storage batteries. Explore potential impacts on battery testing, supplier evaluation and procurement.
- Choosing a Market Trends Dashboard: Data Sources, Coverage, and FreshnessOct 28, 2026Choose a Market Trends dashboard with confidence. Learn how to verify data sources, compare coverage, and assess freshness to find reliable insights for smarter business decisions.